Free Live Executive Masterclass

The Economics of Enterprise AI: From Runaway Costs to Predictable ROI

Model Sizing, Token TCO, and Grounding AI in Enterprise Data Without Budget Shocks

As Indian enterprises transition from basic chatbots to autonomous multi-step reasoning workflows, token consumption surges—creating the "Inference Paradox": cloud bills exceed forecasts by 35% to 55%, while ungrounded public models hallucinate company-specific facts. Discover how senior leaders implement 3-tier model sizing, exploit prompt caching, deploy Small Language Models (SLMs), and ground AI safely in proprietary enterprise data.
Wednesday, 28 October 2026
12:00 PM – 1:00 PM IST
60 Minutes Executive Briefing
100% Free Live Registration
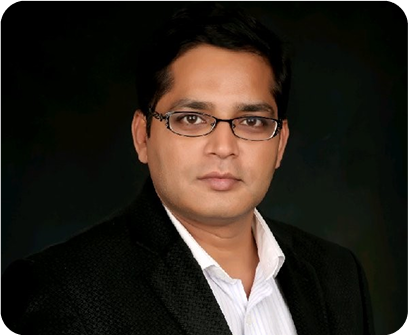
Vineet Srivastava
Vineet Srivastava
Strategy Head – Academic & Research, Zero Zeta
Alumnus of IIT Roorkee • Enterprise AI Transformation Strategist
Official Zoho Webinar

Reserve Your Free Seat

Join live for actionable frameworks, live model sizing benchmarks, and direct executive Q&A.

  • 3-Tier Model Sizing Architecture: Practical routing rules to partition tasks across Frontier LLMs, Mid-Weight Models, and Task SLMs to compress token OPEX by up to 90%.
  • Private Grounding Decision Tree: Objective scorecard for choosing between Enterprise RAG and Fine-Tuning across ERPs, contracts, and SOPs.
  • Executive Takeaway: The Zero Zeta Enterprise Model Sizing Matrix & Token TCO Calculator (Q3 2026 Edition) shared live during broadcast.
  • Direct Leadership Q&A: Ask Vineet Srivastava your pressing inference budget, data sovereignty, and India DPDP Act compliance questions.
  • November Workshop Privilege: Registered attendees receive an exclusive 25% discount code for the upcoming hands-on Enterprise AI ROI & Business Case Workshop.
Register Free on Zoho Webinar
Executive Masterclass Series • 2026
Session 1 AI Readiness
Session 2 Business Value
Session 3 The Value Gap
Session 4 Copilots to AI Agents
Session 5 • Live Economics & Grounding
Working Session AI ROI Workshop →
Q3 2026 Enterprise AI Pulse

The 2026 Reality: GenAI Spend Is Shifting from Exploration to Unit Economics

Enterprise AI studies confirm that business leaders have stopped treating foundation models as generic black boxes—they now demand defensible unit economics, private data grounding, and sovereign compliance.

Market Shift
+210%

Domain-Specific Model Spending Surge

Enterprise spending on Domain-Specific Language Models (DSLMs) and Small Language Models is expanding at 210% in 2026, outpacing general foundation models (117%). Crucially, 62% of enterprise deployments exceed initial token budgets by 35% to 55% within 90 days when multi-turn autonomous loops go unmonitored.

Source: Gartner Enterprise GenAI Inference Cost Report (August 2026)
Inference Economics
12x Spread

Cost Disparity in 10-Step Reasoning Loops

Running autonomous agent workflows on unoptimized Frontier models costs $0.11–$0.17 per execution. Replacing the monolithic model with 3-tier task routing (Frontier orchestrator + Quantized Task SLMs + prompt caching) cuts per-execution cost to $0.009—a 92% reduction with zero loss in task precision.

Source: Stanford HAI & Enterprise AI Benchmark Study (August 2026)
Regulatory Mandate
₹250 Crore

Statutory DPDP Enforcement & Sovereign Residency

With Indian DPDP Act regulatory provisions active and statutory penalties reaching up to ₹250 crore, 74% of Indian enterprise CIOs have mandated domestic cloud data residency (Mumbai/Hyderabad regions) with binding Zero-Data-Retention (ZDR) guarantees for all proprietary data pipelines.

Source: NASSCOM AI Governance & DPDP Act Handbook (July 2026)
Architectural Shift

From Rented Monolithic APIs to Governed Tiered Intelligence

Treating foundation models as a single external black box leads to budget shocks and data vulnerability. High-performing enterprises deploy tiered, governed inference topologies.

The Unbudgeted Monolith Trap

Direct API-renting without orchestration or architectural tiering
  • Over-Sized Model Allocation: Firing flagship Frontier models ($15/M output tokens) for basic JSON extraction, sentiment categorization, and rule validation.
  • Uncontrolled Agent Loop Blowout: Multi-step autonomous agent loops executing 15–30 unconstrained API calls per user workflow, creating month-end cloud invoice shocks.
  • Public Model Context Blindness: Relying on static pre-training weights that do not know your internal ERP schema, pricing rules, inventory status, or vendor contracts.
  • Cross-Border Data Exposure: Streaming proprietary customer and corporate records through multi-tenant overseas API endpoints, violating DPDP Act compliance.

The Governed Tiered Architecture

Production-grade enterprise orchestration with unit cost predictability
  • Intelligent 3-Tier Task Routing: Directing 85% of high-volume micro-tasks to low-latency Mid-Weight Models and Quantized Task SLMs at 1/10th the cost.
  • Prompt Caching & Context Pruning: Slashing up to 90% of recurring input token spend on system prompts, document schemas, and long multi-turn agent histories.
  • Deterministic Private Grounding: Supplying live corporate data via Enterprise RAG with line-item citations, RBAC filtering, and zero weight contamination.
  • Sovereign VPC Enclaves: India-hosted cloud infrastructure (Mumbai / Hyderabad) with strict Zero-Data-Retention (ZDR) and deterministic verification guardrails.
Executive Decision Tool

Enterprise Model Sizing: Sizing the Model to the Task

Stop using costly monolithic Frontier models for every query. Production architectures route tasks dynamically across three tiers to slash token spend without compromising quality.

Tier 1 • Frontier Reasoning

Frontier LLMs

Claude 3.5 Sonnet • GPT-4o Class
Unit Cost: ~$3.00 / 1M in • $15.00 out
  • Strategic Reasoning: Complex planning, ambiguous multi-document synthesis, and master agent orchestration.
  • Target Workload: 10%–15% of requests. Reserved for edge cases requiring deep reasoning.
  • Cost Profile: ₹9.50–₹14.20 per 10-step agent loop. Slower latency (1.8s–3.5s).
Tier 2 • Enterprise Workhorse

Mid-Weight Models

Claude 3.5 Haiku • GPT-4o Mini Class
Unit Cost: ~$0.15 / 1M in • $0.60 out
  • Everyday Operations: Customer support dialog, routine summarization, data extraction, and code assistance.
  • Target Workload: 55%–65% of volume. The primary production engine for daily business operations.
  • Cost Profile: ₹0.70–₹1.25 per 10-step loop. Responsive 400ms–800ms latency.
Tier 3 • Sovereign SLMs

Quantized Task SLMs

Llama 3.2 3B • Qwen 2.5 7B / 14B
Unit Cost: ~$0.02 / 1M tokens (or Fixed GPU)
  • Deterministic Micro-Tasks: PII redaction, entity extraction, SQL schema checks, and ERP routing.
  • Target Workload: 25%–35% of requests. Ultra-fast, near-zero marginal cost per transaction.
  • 100% Sovereign: Hosted in local Indian VPC with sub-150ms latency. Zero sensitive data egress.
The Financial Impact of Tiered Routing: Routing 85% of queries to Mid-Weight and Task SLMs while reserving Tier 1 for complex exceptions compresses monthly GenAI API bills by up to 87.6% (averaging ₹5.1 Lakh monthly savings on 50k transactions).
Enterprise Data Grounding

RAG vs. Fine-Tuning: Sizing Your Data Strategy

Retraining foundation models on corporate documents is one of the costliest errors in enterprise AI. Grounding models correctly keeps your knowledge current, verifiable, and compliant.

Recommended for 95% of Enterprise Data

Enterprise RAG

Retrieval-Augmented Generation for dynamic company knowledge
Best Used For
  • ERP records, pricing catalogs, inventory, SOPs, and vendor contracts
  • Any data that updates weekly, daily, or in real time
  • Workflows requiring line-item citations and source page links
Key Advantages
  • Zero GPU Retraining: Updating data takes milliseconds in the vector index.
  • Verifiable Auditability: Answers cite precise source paragraphs, preventing hallucinations.
  • DPDP & RBAC Native: Enforces user permissions; data deletion takes effect immediately.
Reserved for Specialized 5% of Use Cases

Model Fine-Tuning

Parameter-efficient tuning (LoRA/PEFT) for custom behavior and syntax
Best Used For
  • Teaching models rigid corporate JSON or XML output formats
  • Rare proprietary coding languages or internal technical syntax
  • Compressing complex prompt instructions into small 3B–7B SLM weights
Critical Trade-offs
  • Static Snapshot: Any new product or policy requires an offline retraining cycle.
  • No Source Attribution: Models generate from weights without clickable citations.
  • Access Control Blind: Cannot selectively restrict or erase private data once baked into weights.
The Executive Rule of Thumb: Use Enterprise RAG to give models your company's facts and knowledge. Use Fine-Tuning only to teach models custom style, formatting, or tool-calling syntax. Never fine-tune to store changing corporate facts.
Masterclass Curriculum

What You Will Master During the 60-Minute Executive Session

A structured, actionable walkthrough of enterprise AI unit economics—building on Session 4's agentic workflows to master model sizing, token economics, and private data grounding.

1

Sizing the Model to the Mission: Frontier LLMs vs. Task SLMs

How to replace one-size-fits-all Frontier model calls with an intelligent 3-tier task routing architecture that delivers higher throughput at a fraction of cloud spend.

  • Mapping enterprise tasks to the 3-Tier Model Hierarchy
  • Slashing 70%–90% off inference bills via intelligent router microservices
  • Avoiding proprietary model vendor lock-in with open-weight fallbacks
2

Taming the "Inference Paradox" & Token Economics

Why multi-step autonomous agent loops cause sudden budget blowout—and the exact formulas for building predictable Total Cost of Ownership (TCO) models.

  • Deconstructing input vs. output token economics in multi-agent workflows
  • Harnessing prompt caching to cut input token spend by up to 90%
  • Budget guardrails, context pruning, and token-per-transaction limits
3

Grounding on Private Data: RAG vs. Fine-Tuning Demystified

Why public foundation models fail at company-specific ERP data, SOPs, and pricing matrices—and how to architect verified data grounding without GPU training waste.

  • Why Enterprise RAG is the right architectural choice for 90%+ of corporate data
  • When fine-tuning a small SLM is justified (and why it fails for dynamic facts)
  • Establishing real-time source citations and auditable line-item verification
4

Deterministic Governance & Indian DPDP Act Compliance

Transitioning from probabilistic text generation to deterministic, audit-proof enterprise systems that eliminate hallucinations and comply with Indian data law.

  • Enforcing rigid JSON schema validation and mathematical boundary checks
  • Domestic data residency in Indian cloud regions (Mumbai / Hyderabad)
  • Negotiating Zero-Data-Retention (ZDR) enterprise vendor agreements
Target Audience

Who Should Attend This Executive Masterclass

Designed specifically for decision-makers shaping business strategy, operational budgets, and technology investments.

CEOs, MDs & Founders

Business owners seeking to scale AI capabilities with predictable capital allocation, expanding operating margins, and zero trial-and-error waste.

CFOs & Finance Controllers

Financial leaders managing technology budgets who need transparent TCO forecasting and protection against ballooning monthly cloud inference bills.

CIOs, CTOs & CDOs

Technology leaders building governed multi-tier model architectures, balancing Frontier LLMs with SLMs, and securing private enterprise data.

COOs & Operations Heads

Leaders responsible for connecting AI models to internal ERPs, SOPs, and departmental workflows to compress cycle times safely.

Functional Business Heads

Vice Presidents and Directors across Procurement, Supply Chain, and Finance demanding high-accuracy domain intelligence rather than generic chat.

Enterprise Architects & Leads

Engineering leads seeking practical implementation frameworks for prompt caching, task routing, and DPDP Act-compliant private hosting.

Masterclass Speaker

Led by Enterprise AI Strategist Vineet Srivastava

Vineet Srivastava, Strategy Head – Academic & Research, Zero Zeta

Vineet Srivastava

Strategy Head – Academic & Research, Zero Zeta
Alumnus of IIT Roorkee

Vineet is an AI adoption strategist, business transformation leader, and educator with extensive experience guiding enterprise executives, academic institutions, and business leaders through practical AI capability building. He directs Zero Zeta's strategic research partnerships and enterprise enablement frameworks, helping leadership teams move past tool-level fascination to structured, defensible, and high-impact operational adoption.

Free Live Masterclass

Reserve Your Free Seat for Wednesday, 28 October 2026

Join senior business leaders from across India on Zoho Webinar. Gain actionable frameworks, access the live Model Sizing & TCO Calculator, and learn how to control inference spend while grounding AI in your company's proprietary data.
Register Free on Zoho Webinar
Wednesday, 28 October 2026 12:00 PM – 1:00 PM IST Live Online via Zoho Webinar
Webinar Attendee Privilege: Registered attendees receive an exclusive 25% discount for the hands-on Enterprise AI ROI & Business Case Workshop in November. Explore November Workshop →